Practice area · Kansas City and remote

AI Agentic Solutions

An agent that is 95% accurate per step fails most twenty-step tasks. Reliable agents come from design, not just a better model: verification, retries, escalation to a person and evaluation sets large enough to catch regressions. Vector 1 designs and evaluates agentic systems with the economics in view, measured as cost per completed task.

What we do

  • Agent design: planning, tool use, memory and human escalation
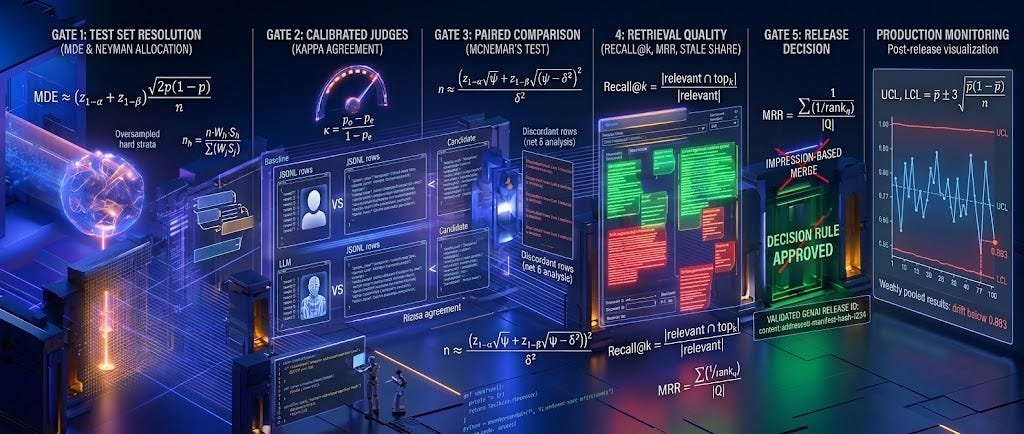
  • Verification and evaluation: test sets sized to detect real regressions
  • Cost per completed task, not cost per call
  • Back-office automation such as reconciliation, intake and document processing

Talk about your project

Tell us what you're trying to measure, forecast or decide. We work with teams in Kansas City and remotely, and we reply within two business days.

Email [email protected]

Try it: interactive demos

Common questions

Why do AI agents fail on long tasks?

Errors compound. If each step succeeds 95% of the time, a 20-step task succeeds only about 36% of the time. Verifiers, retries and escalation to a person raise end-to-end reliability, at a cost that should be measured per completed task.

How large should an agent evaluation set be?

Large enough to detect the change you care about. A few hundred test questions can miss a regression of several percentage points, so the size of an evaluation set should come from a power calculation, like any experiment.

Do you work with teams outside Kansas City?

Yes. Vector 1 is based in Kansas City and works with teams in the metro and remotely.